Embrace & Extend

To Walled Gardens

It is hard to imagine now, given the walled gardens we spend so much of our time in, but way back at the beginning of the web, people really cared about open standards. You could almost implement a new browser that would work on current and future websites, as long as you and the site both supported the HTTP and HTML standards of the day. [8][9] However, any self-respecting commercial software company treated open standards cynically. Microsoft and Apple paid lip service to standards, but would actually go to great efforts to embrace and extend. Implement the standard, yes, but then encourage developers to use proprietary extensions, libraries, and functionality to force lock-in and increase switching costs. Netscape extended HTML. [12] Microsoft shipped a Windows-only Java runtime [10] and a Kerberos with proprietary fields. [13] Sun kept control of Java while calling it open. [14] AOL and CompuServe ran closed networks. Microsoft’s Halloween documents stated the goal directly: turn open protocols back into proprietary ones. [4]

It’s just good business. Today’s walled gardens epitomize this approach: no one even pretends to have a standard API, data exchange, or RPC format between, say, Instagram and Snapchat. Add app stores on mobile and the lock-in is all the more extreme. TCP/IP, HTTP, HTML, SMTP, and TLS stayed open, but when vendors could no longer extend the higher-level protocols, they built closed systems on top: app stores, messaging networks, social feeds, ad platforms. A walled garden is the fallback for a company that failed to capture the standard underneath. Lock-in became entrenched, and nothing was going to change it. Until it did.

STDOUT and STDIN

The most important technology of the last ten years is stunningly, shockingly, anti-marketingly open. I’m not sure there’s an ANSI committee sitting anywhere deliberating, but de facto standards have always been as important. The closest thing we have ever had to AGI is most useful via a well-known, pseudo-standardized interface: Chat, duh. [11] To get the most work done with ChatGPT, Claude, or Gemini, you fire up a REPL that accepts text and attachments. The server side does its computation and tool calls, and responds similarly with text and attachments. It’s like System V, baby.

Coding agents are the most important new developer interface in years, built by companies worth hundreds of billions of dollars. A coding agent is a language model in a loop with tools: it reads files, runs shell commands, edits code, reads the output, and repeats. Claude Code, Codex CLI, Gemini CLI, and independent agents like Goose all work the same way. Switching between them means changing a command name and possibly renaming an instruction file. [1][2][5] The models behind them differ in accuracy, speed, and price. The interface, the de facto standard, does not. By the measure of the 1990s, coding agents should already be fragmented into proprietary, mutually incompatible walled gardens. But they’re not.

  • The loop and tool set are the same across vendors: read, search, edit, write, run a shell command, fetch a URL, and ask permission.
  • OpenAI and Google release their CLIs under Apache 2.0. [1][2]
  • Repository instructions converged on AGENTS.md. Tool integration converged on MCP. OpenAI and Anthropic donated both to the Linux Foundation’s Agentic AI Foundation in December 2025. [3][6][7]
  • Third-party agents call the same model APIs as the first-party ones.

No vendor has shipped an incompatible tool schema, an instruction format only its own agent reads, or a plugin system that only works in its own CLI.

I cannot give frontier AI lab leadership much credit here. There has never been any earnest hacker or interoperability ethos demonstrated in the upper echelons of VC-backed Shiny Ball LLCs. Maybe it was a happy accident? And if so, how have the sorta-geniuses let this go on so long?

Next

We are supposed to believe the vendors sell tokens, not interfaces, not harnesses. They subsidize our Max subscriptions, nudge the API plans upward in price, and eventually expect to own the whole space. (Insert here the obviously-bullshit, talking-your-book marketing argument about the forthcoming singularity, 2026 style.)

Soon the walls are going up around the interface, the chat, as the 90s pattern predicts: OpenAI or Anthropic release a higher-level tool like a coworker that — importantly — is the only way to get at the AGI-grasping model du jour. Like if Fable were only usable via Anthropic’s heavy iOS client, and only via Dots or something. We will move toward closed services around one lab’s server side as soon as someone wises up. Or as soon as we get a little blip in the AI stock bubble.

References

  1. OpenAI, Codex CLI source and license: github.com/openai/codex
  2. Google, Gemini CLI source and license: github.com/google-gemini/gemini-cli
  3. Linux Foundation, Formation of the Agentic AI Foundation, December 9, 2025
  4. Eric S. Raymond, The Halloween Documents
  5. Block, Goose source: github.com/block/goose
  6. OpenAI, OpenAI co-founds Agentic AI Foundation, donates AGENTS.md, December 9, 2025
  7. Anthropic, Donating MCP to the Agentic AI Foundation, December 9, 2025
  8. T. Berners-Lee and D. Connolly, RFC 1866: Hypertext Markup Language 2.0, November 1995
  9. T. Berners-Lee, R. Fielding, and H. Frystyk, RFC 1945: Hypertext Transfer Protocol, HTTP/1.0, May 1996
  10. U.S. District Court for D.C., U.S. v. Microsoft: Court’s Findings of Fact, November 1999, Section VI (Java)
  11. Google, Gemini API: OpenAI compatibility
  12. Dave Raggett, My involvement with the early days of the Web, W3C, December 2004
  13. Network World via Computerworld, Interoperability issues bite Win 2000 Kerberos scheme
  14. InfoWorld, Sun to retain grip on Java, December 8, 1999
Sketches for Streaming Market Data

Sketches have always struck me as kinda magic.

With an infinite time-series of data, we usually keep a window: the last 20 bars, the last 1,000 ticks, the last five minutes. Then recompute whatever statistic you want over the window. This is fine until you have thousands of symbols, long lookbacks, or tight loops where sorting is expensive.

A lot of statistics don’t require a window. You can reduce a stream to a small state, update that state when a new observation arrives, and throw the observation away. This is what skream does. It’s a Clojure library for streaming statistics I wrote a while back.

Exponential Mean and Variance

A simple moving average remembers everything in its window and then forgets the oldest observation. In an exponential average, old observations decay instead of vanishing.

The important parameter is the half-life: how many observations until an observation is worth half as much? If the half-life is h, then alpha = 1 - 0.5^(1/h). skream takes alpha directly. The state is just the current EMA plus a count.

(require '[skream.core :as sk])

(def s
  (-> (sk/create-skream)
      (sk/track-exponential-moving-average 0.05)))

(def s
  (reduce sk/add-num s returns))

(get s [:ema 0.05])

The default alpha is 0.125. Keep one Skream per instrument and update it on every return. Variance is a separate tracker:

(def s
  (-> (sk/create-skream)
      sk/track-variance
      sk/track-standard-deviation))

(def s
  (reduce sk/add-num s returns))

(:var s)
(:stdev s)

Three numbers per instrument cheaper than keeping the history around. See also the infamous infinite-memory issue in Pandas. And skream has the usual cumulative mean, higher moments, skewness, and kurtosis stats too.

Quantiles Without a Window

The P² algorithm, from Jain and Chlamtac, estimates a quantile using five markers. The markers track the minimum, maximum, desired quantile, and two points around it. New observations update their positions. When the markers get out of place, their heights are adjusted using parabolic interpolation. The amount of state doesn’t grow with the number of observations.

The skream version is straightforward:

(def s
  (-> (sk/create-skream)
      (sk/track-quantile-ish 0.95)))

(def s
  (reduce sk/add-num s prices))

(get s [:quantile 0.95])

For the median, there is a convenience function:

(def s
  (-> (sk/create-skream)
      sk/track-median-ish))

(def s
  (reduce sk/add-num s prices))

(:median s)

After 25 SPY closes, skream produces roughly:

{:quantile 193.72229
 :qs [187.55 191.74467 193.72229 195.5992 196.48]
 :ns [1 7 13 19 25]}

:qs are the marker heights. :ns are their positions. The middle marker is the median.

There are two catches. P² estimates one quantile, so if you want the 5th, 50th, and 95th percentiles, you run three estimators. More importantly, P² isn’t mergeable. If you have a cluster processing different pieces of a feed and want one global quantile, P² is the wrong tool. Use KLL, t-digest, or another mergeable sketch.

Count Things Without Counting Everything

A Count-Min sketch is a small array of counters plus a few hash functions. Each key increments one counter in each row. To estimate the count, take the minimum across the rows. It can only overestimate. With width w = e/ε and depth d = ln(1/δ), the error is bounded by εN with probability 1−δ.

skream calls this track-element-counts-ish:

(def s
  (-> (sk/create-skream)
      (sk/track-element-counts-ish 256 128)))

(def s
  (reduce sk/add-num s symbols))

(sk/get-element-count-ish s "AAPL")

This is useful when the alternative is keeping a giant hash table around just to discover that one symbol generated an unusually large number of messages.

HyperLogLog estimates cardinality: how many distinct things have I seen? Unique order IDs, unique symbols, unique clients, whatever. With m registers, the standard error is approximately 1.04 / sqrt(m). Sixteen thousand registers gets you roughly 0.8% error while consuming about 12 KB.

In skream, the number of registers is 2^b, so 14 bits gives 16,384 registers:

(def s
  (-> (sk/create-skream)
      (sk/track-distinct-value-count-ish 14)))

(def s
  (reduce sk/add-num s order-ids))

(get s [:hll 14])

The exact answer might require millions of IDs. The approximate answer requires 16,384 registers.

A Bloom filter answers one question: have I seen this before? It has false positives but no false negatives. That makes it useful for feed replay and deduplication. If it says “no,” you haven’t seen the message. If it says “yes,” maybe you have.

skream uses multiple SHA-1-derived hashes for this:

(def s
  (-> (sk/create-skream)
      (sk/track-member-ish? 6 8)))

(def s
  (reduce sk/add-num s message-ids))

(sk/member-ish? s message-id)

The 6 is the number of bits used for each hash bucket and 8 is the number of hash functions. Again, fixed memory, but an arbitrarily long stream.

Feature Hashing

Feature hashing is another sketch, although it usually gets presented as a machine-learning trick rather than a streaming data structure. Suppose you have a stream of sparse categorical features: symbols, venues, order types, words, whatever. Instead of growing a dictionary from feature names to columns, hash each feature into one of m buckets and keep only the resulting vector: feature → hash → bucket → update.

If two features land in the same bucket, they share share a model parameter or set of weights. With signed hashing, a second independent hash assigns each feature either +1 or -1, so a collision either adds or subtracts their contributions. This is useful because collisions do not systematically inflate a bucket: over many collisions, the random signs make the cross-terms tend to cancel, mostly preserving inner products. The parameter tying also reduces the model’s degrees of freedom, so collisions can act as regularization. The two effects are distinct: the random sign controls the distortion caused by collisions; the shared parameter constrains the model.

This is the same trick as the other sketches here: throw away information deliberately so the state stays bounded. Feature hashing just makes the trade particularly obvious. You’re compressing an unbounded feature space while constraining the model at the same time.

Mutual Information

Correlation is easy but less useful when the relationship is nonlinear. Mutual information can find nonlinear dependence. A simple streaming approximation is to keep fixed histograms of (x, y) and their marginals, then calculate Σ p(x,y) log(p(x,y) / (p(x)p(y))) when you want the answer.

skream does this with multiple Skreams: build a histogram for each series, a co-histogram for the pair, and then track the mutual information between them.

(def ms
  (sk/create-multi-skream))

(def ms
  (-> ms
      (sk/assoc-multi-skream :x (sk/create-skream))
      (sk/assoc-multi-skream :y (sk/create-skream))
      (sk/track-multi-mutual-information :x :y -5.0 5.0 32)))

(def ms
  (reduce (fn [ms [x y]]
            (sk/add-multi-num ms :x x :y y))
          ms
          observations))

Mutual information estimates are sensitive to binning and biased when there are not enough observations per bin. Change the bins and you can change the answer, so use it to rank things worth investigating.

Wrapup

Prices are discrete. P² interpolation can produce values between ticks. That’s mathematically cute but buggy.

Histogram methods have their own problem: they depend on the bins. skream has Gaussian-spaced bins, which are useful when you want more resolution around the center of the distribution.

So why bother? Because most streaming systems don’t need the data. They need a statistic about the data. Keeping every observation is often just an indirect way of calculating that statistic later, at considerably greater expense.

A fixed-memory estimator turns data → storage → sorting → calculation into data → update → discard. The second version is generally cheaper, faster, and much harder to accidentally turn into a memory leak.

skream contains the usual collection: moments, variance, skewness, kurtosis, EMA, P² quantiles, Bloom filters, Count-Min, HyperLogLog, histograms, and histogram mutual information. Everything is fixed-memory except the simple moving average, because a simple moving average is definitionally a moving window.

Notes on The Man Who Solved The Market (Jim Simons)

Like seemingly everyone who works on the buy side, I have been reading the Zuckerman book about Jim Simons of Renaissance. The book spends a lot of time with the big personalities who have worked at Renaissance over the years. However there are some mathematical and technology hints:

Jim Simons’s academic field is geometric invariants in algebraic geometry.

Renaissance Technology worked with hidden Markov models, fit using the Baum-Welch algorithm. This algorithm has a Bayes update step, and a backward & forward process that feels like backprop. They also used high-dimensional kernel regression.

Henry Laufer worked with (vector) embeddings, very early. He also pushed for a single cross-asset and cross-asset-class model, so they could use all the cleaned “pricing” (market) data. They included assets with known bad data, but assets that nonetheless looked like existing assets in the model. This is maybe what we would call clustering, now-a-days. Everyone had access to the source code, even the administrative staff at first.

They tempted academics by working just one day per week, to see if they found trading interesting. They explicitly avoided trying to find economic sensibility for their strategies, but still followed a “scientific” method.

René Carmona imputed market data, which seems controversial.

Jim Simons invested in private companies alongside the systematic trading, especially in technology companies. This is probably because of the Nasdaq bubble.

They used a simple day-of-week seasonality model, at least for their futures trading.

They provided liquidity when “locals” de-risk, being in the “insurance business”.

They had a betting algorithm around the probability of moves in futures, not used for stocks at first. This was presented as opposed to statistical arbitrage with a factor model.

Their stock transaction cost model was the “secret weapon”. It was self-correcting, by “searching for buy-or-sell orders to nudge the portfolio back”. This increased their holding period to two days, on average. The strategy had very low capacity at first, however. In general they were not the best at trading, but at “estimating the cost of a trade”.

Around the time of the Nasdaq bubble bursting, they were trading 8,000 stocks. However this strategy was only 10% of the business. The futures strategy was still the mainstay, which was probably their chartist model.

Their use of basket options were 1) a tax optimization, but also 2) a way to cap downside, 3) isolate risk, and 4) increase leverage.

The internal Medallion fund is short-term, capped at $5b capital with all external clients eventually bought-out. The maximum capital is difficult to reconcile with Jim Simons’s compensation motivation, so it probably reflects limited capacity of the strategy, which means it trades in less liquid, smaller stocks and futures. In 2002 they were running 12x leverage in Medallion ($5b capital, $60b exposure given options).

They sought out astronomers because of their understanding of low signal-to-noise problems. Their named “Déjà Vu” strategy seems like a pairs or cointegration strategy.

Their strategy gets a 50.75% hit rate.

Why write this book now? Jim Simons is nearing the end of his career. Could also be transparency after the Mercers helped get Trump elected.

They at least use the terminology of risk factors and baskets: “RenTec decrypts them [inefficiencies]. We find them across time, across risk factors, across sectors and industries.”

The author uses strange terminology, suggesting that Zuckerman has actually not talked with many quants. For example, “trenders” for momentum style traders, and “data hunters” instead of “data scientists”.

Also the anecdote about Magerman unleashing “a computer virus that was infecting Renaissance’s computers” is clearly bullshit, and in a way that makes me doubt the author’s understanding of technology in general.

Happy Birthday, Hipsteraunt

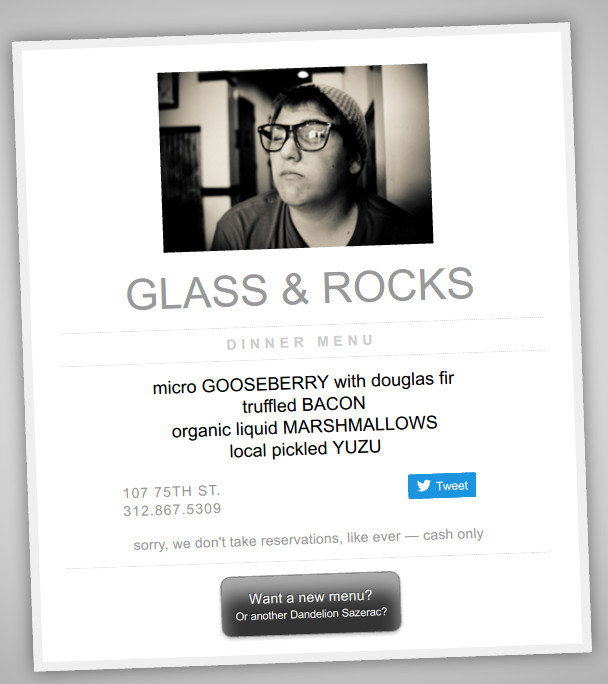
Last month was the two year anniversary of the website Hipsteraunt, which I built with my friend Lance Arthur. He did the design, I did the random menu generation. It is a quirky bit of AI and NLP under-the-hood, so a user gets menus featuring free-range suspended chicken feet, truffled shisito pepper with achiote, and marshmallow crudo, at a place with an ampersand in its name. The inspiration had been a particular dinner out in San Francisco, at an immensely overrated restaurant. But it could have been Brooklyn or the West Loop. I am a quant & machine learning researcher by happy vocation, but also a chef by training. (Le Cordon Bleu with honors, thank you.) So the term “foodie” has always struck me as what privileged folks call themselves when they like to eat fancy food, but would not be caught dead hanging out with a line cook.

Hipsteraunt remains a tender satire of a certain sort of fetishized dining out. It was meant to be an acerbic call to check-your-privilege, together with a reminder that nothing in food is new. No combination of ingredients or flavors has not been tried a thousand times before. Even offal and the Asian flavors everyone loves to exoticize. (Awkward…) We lived through the fusion cuisine of the 1980s, remember? In hindsight, it might have cut a bit too close to the bone. The site garnered plenty of attention, but less heady pokes like the fake Guy Fieri menu and the brilliant Jacques le Merde have been far more successful. An annoying bug with making menu URLs permanent snagged things up the first couple weeks, too. Nonetheless on Hipsteraunt’s second birthday, I celebrate by raising an artisanal cocktail (a lemongrass aviation, perhaps) and toasting the addition of a few new ingredients: Keep an eye out for those trendy signifiers of faux-edgy cuisine we all love, like burrata and purslane, za’atar and togarashi. Goodbye ginger, goodbye almond milk. But it looks like bacon is still there.


New Sentiment Dataset

The good folks in Stanford’s Natural Language Processing Group have built a powerful new dataset for a paper being presented at the EMNLP conference in Seattle next month. The underlying foundation of the dataset is not particularly exciting, being yet another corpus of labeled movie reviews: The review sentence “Stealing Harvard doesn’t care about cleverness, wit or any other kind of intelligent humor” is provided along with its negative sentiment label, for example. What is more interesting is the corpus providing sentiment labels at every level of composition. So for the same sentence, the dataset also provides a distinct sentiment label for the sub-phrase “any other kind of intelligent humor” which is actually positive. Hence the dataset is a treebank, not just your typical corpus. A lot of Mechanical Turk wrangling went into this! This compositional and recursive labeling is a great resource for training contextual models, especially ones that go beyond the bag-of-words legacy.

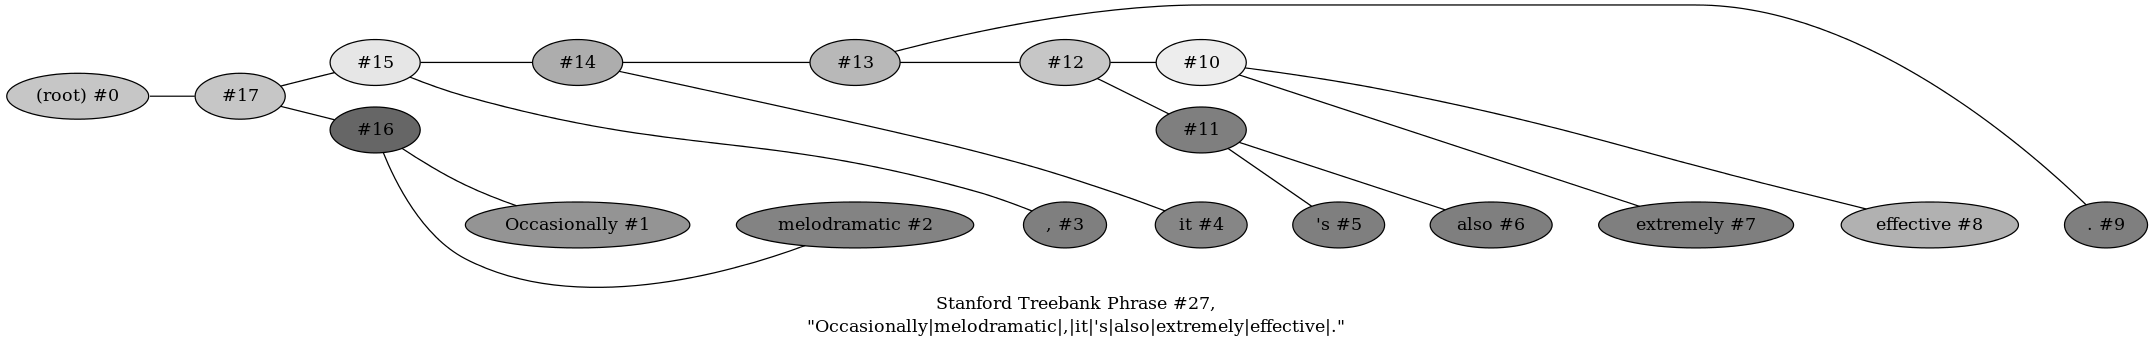
Here at Trending we are experimenting with an online, regularized, high-dimensional linear approximation to the Stanford paper’s tensor RNN model, one that lets us use the whole Vowpal Wabbit stack. Next month they plan to release some (Matlab) code to parse the treebank, but have already released the data itself. Therefore I put together a simple Ruby module to parse the treebank, for your own statistical NLP, sentiment and machine learning projects. It includes a bit of Graphviz logic to render phrase trees and their sentiment as SVG:

The module is hosted on Github at “http://github.com/someben/treebank/” under a nice Free license.

Hashing Language

How do you build a language model with a million dimensions?

The so-called “hashing trick” is a programming technique frequently used in statistical natural language processing for dimensionality reduction. The trick is so elegant and powerful that it would have warranted a Turing Award, if the first person to use the trick understood its power. John Langford cites a paper by George Forman & Evan Kirshenbaum from 2008 that uses the hashing trick, but it may have been discovered even earlier.[1] [2] Surprisingly most online tutorials and explanations of the hashing trick gloss over the main insights or get buried in notation. At the time of this writing, the Wikipedia entry on the hashing trick contains blatant errors.[3] Hence this post.

Hash, Man

A hash function is a programming routine that translates arbitrary data into a numeric representation. Hash functions are convenient, and useful for a variety of different purposes such as lookup tables (dictionaries) and cryptography, in addition to our hashing trick. An example of a (poor) hash function would map the letter “a” to 1, “b” to 2, “c” to 3 and so on, up to “z” being 26 — and then sum up the numbers represented by the letters. For the Benjamin Franklin quote “beware the hobby that eats” we get the following hash function output:

(beware) 2 + 5 + 23 + 1 + 18 + 5 +
(the) 20 + 8 + 5 +
(hobby) 8 + 15 + 2 + 2 + 25 +
(that) 20 + 8 + 1 + 20 +
(eats) 5 + 1 + 20 + 19
= 233

Any serious hashing function will limit the range of numbers it outputs. The hashing function we used on Benjamin Franklin could simply take the first two digits of its sum, the “modulo 100” in programming terms, and provide that lower number as its output. So in this case, the number 233 would be lopped-off, and the hash function would return just 33. We have a blunt quantitative representation or mapping of the input that is hopefully useful in a statistical model. The range of this hashing function is therefore 100 values, 0 to 99.

Now a big reason to choose one hashing function over another is the statistical distribution of the output across the function’s range, or uniformity. If you imagine feeding in a random quote, music lyric, blog post or tweet into a good hashing function, the chance of the output being any specific value in the range should be the same as every other possible output. For our hashing function with a 0-99 range, the number 15 should be output about 1% of the time, just like every other number between 0 and 99. Note that our letter-summing hash function above does not have good uniformity, and so you should not use it in the wild. As an aside, keep in mind that certain hash functions are more uniform on bigger input data, or vice-versa.

Another reason to favor one hashing function over another is whether or not a small change in the input produces a big change in the output. I call this concept cascading. If we tweak the Benjamin Franklin quote a little bit and feed “beware the hobby that bats” into our silly hash function, the sum is now 230, which gets lopped-off to 30 within the hash’s output range. This modest change in output from 33 or 30 is another sign that our toy hash function is indeed just a toy. A small change in the input data did not cascade into a big change in the output number.

Here the important point is that a good hashing function will translate your input into each number in its output range with same probability (uniformity), and a small change in your input data will cause a big change in the output (cascading).

That’s Just Zipf-y

In human languages, very few words are used very frequently while very many words are very rare. For example, the word “very” turns up more than the word “rosebud” in this post. This relationship between word and frequency is very convex, non-linear or curved. This means that the 25th most common word in the English language (“from”) is not just used a little more frequently than the 26th most common word (“they”), but much more than the lower ranked word (26th).

This distribution of words is called Zipf’s Law. If you choose a random word from a random page in the Oxford English Dictionary, chances are that word will be used very rarely in your data. Similarly if you were to choose two words from the OED, chances are both of those words will not be common.

The Trick

If you are doing “bag-of-words” statistical modeling on a large corpus of English documents, it is easy find yourself accommodating thousands or millions of distinct words or ngrams. For example the classic 20 newsgroup corpus from Ken Lang contains over 61,000 different single words, and exponentially more two-word bigrams. Training a traditional statistical model with 61,000 independent variables or dimensions is computationally expensive, to say the least. We can slash the dimensionality of a bag-of-words model by applying Zipf’s Law and using a decent hashing function.

First we identify a hashing function with an output range that matches the dimensionality we wish the data had. Our silly hashing function above output a number from 0 to 99, so its range is 100. Using this function with the hashing trick means our statistical bag-of-words model will have a dimensionality of 100. Practically speaking we usually sit atop an existing high-quality hashing function, and use just a few of the least significant bits of the output. And for computational reasons, we usually choose a power of two as our hash function output range and desired dimensionality, so lopping-off the most significant bits can be done with a fast bitwise AND.

Then we run every word or ngram in the training data through our adapted hashing function. The output of the hash becomes our feature, a column index or dimension number. So if we choose 28 (two -to-the-power-of- eight) as our hashing function’s range and the next ngram has a hash of 23, then we set our 23rd independent variable to the frequency count (or whatever) of that word. If the next hash is the number 258, we map to the output 3 at the bit level for the third dimension, or 258 = 255 + 3 = 255 + (258 MOD 255) more mathematically. Our statistical NLP model of the 20 newsgroup corpus suddenly goes from 61,000 to only 256 dimensions.

Wait a Sec’…!

Hold on, that cannot possibly work… If we use the numeric hash of a word, phrase or ngram as an index into our training data matrix, we are going to run into too many dangerous hash collisions, right?

A hash collision occurs when two different inputs hash to the same output number. Though remember that since we are using a good hashing function, the uniformity and cascading properties make the chance of a hash collision between any two words independent of how frequently that word is used. Read that last sentence again, because it is a big one.

The pair of words “from” & “rosebud” and “from” & “they” each have the same chance of hash collision, even though the frequency with which the four words turn up in English is varied. Any pair of words chosen at random from the OED has the same chance of hash collision. However Zipf’s Law says that if you choose any two words randomly from the OED, chances are one of the words will be very rare in any corpus of English language documents. Actually both words will probably be infrequent. Therefore if a collision in our hash function’s output occurs, the two colliding words are probably oddballs.

Two Reasons it Still Works

Statistical NLP bag-of-words models that use the hashing trick have roughly the same accuracy as models that operate on the full bag-of-words dimensionality. There are two reasons why hash collisions in the low-dimensional space of the hash function’s output range do not trash our models. First any collisions that do occur, probably occur between two rare words. In many models, rare words do not improve the model’s regression / classification accuracy and robustness. Rare words and ngrams are said to be non-discriminatory. Now even if rare words are discriminatory in your problem domain, probability suggests the rare words do not co-occur in the same document. For this reason, the two rare words can be thought of as “sharing” the same representation in the model, whether this is decision tree sub-trees or a coefficient in a linear model. The Forman & Kirshenbaum paper says “a colliding hash is either unlikely to be selected as a feature (since both words are infrequent) or will almost always represent the word that led the classifier to select it.”

We cannot use the hashing trick for dimensionality reduction in every statistical model. Zipf’s Law means most features or independent variables in a bag-of-words representation equal zero. In other words, a point in the dimensional space of the bag-of-words (a “word vector”) is generally sparse. Along these lines, John Langford says the hashing trick “preserves sparsity.” For a random specific word, the chance of two random examples both having a non-zero value for that feature is low. Again this is because most words are rare.

The hashing trick is Zipf’s Law coupled with the uniformity & cascading properties of a good hash function, and using these to reduce the dimensionality of a sparse bag-of-words NLP model.

Notes

[1] Actually the first public version of the hashing trick John Langford knew of was in the first release of Vowpal Wabbit in back in 2007. He also points out that the hashing trick enables very efficient quadratic features to be added to a model.
[2] Jeshua Bratman pointed out that the Sutton & Barto classic textbook on reinforcement learning mentions the hashing-trick way back in 1998. This is the earliest reference I have yet found.
[3] “the number of buckets [hashing function output range] M usually exceeds the vocabulary size significantly” from the “Hashing-Trick” Wikipedia entry, retrieved on 2013-01-29.

Sequential Learning Book

Things have been quiet around here since the winter because I have been focusing my modest writing and research skills on a new book for O’Reilly. We signed the contract a few days ago, so now I get to embrace a draconian authorship schedule over the next year. The book is titled Sequential Machine Learning and will focus on data mining techniques that train on petabytes of data. That is, far more training data that can fit in the memory of your entire Hadoop cluster.

Sequential machine learning algorithms do this by guaranteeing constant memory footprint and processing requirements. This ends up being an eyes-wide-open compromise in accuracy and non-linearity for serious scalability. Another perk is trivial out-of-sample model validation. The Vowpal Wabbit project by John Langford will be the book’s featured technology, and John Langford has graciously offered to help out with a foreword. Therefore the book will also serve as a detailed tutorial on using Vowpal Wabbit, for those of us who are more coder or hacker than statistician or academic.

The academic literature often uses the term “online learning” for this approach, but I find that term way too confusing given what startups like Coursera and Khan Academy are doing. (Note the terminology at the end of Hilary Mason’s excellent Bacon talk back in April.) So, resident O’Reilly geekery-evangelist Mike Loukides and I are going to do a bit of trailblazing with the more descriptive term “sequential.” Bear with us.

From the most basic principles, I will build up the foundation for statistical modeling. Several chapters assume statistical natural language processing as a typical use case, so sentiment analysis experts and Twitter miners should also have fun. My readers should know computers but need not be mathematicians. Although I have insisted that the O’Reilly toolstack support a few of my old-school LaTeX formulas…

Dan Rice on How the Experts May Not Always Be Right: A Story About the Discovery of Preclinical Alzheimer’s Disease in 1991

Machine learning can be a check on conventional thinking, if we let it.

On the new analytics Linkedin group started by Vincent Granville, Dan Rice wrote a personal account of his frustrations with the Alzheimer’s research of 20 years ago, before we understood more about the preclinical period of the disease:

The problem that I have with domain expert knowledge selecting the final variables that determine the model is that it no longer is data mining and it often is no longer even good science. From the time of Galileo, the most exciting and important findings in what we call science are those data-driven findings that prove the experts wrong. The problem is that the prior domain knowledge is usually incomplete or even wrong, which is the reason for research and analytics in the first place. I understand that the experts are helpful to generate a large list of candidate variables, but the experts will often be wrong when it comes to determining how, why and which of these variable combinations is causing the outcome.

I had an experience early in my research career that has made me forever distrustful of the expert. I was doing brain imaging research on the origins of Alzheimer’s disease in the early 1990’s and all the experts at that time said that the cause of Alzheimer’s disease must be happening right when the dementia and serious memory problems are observed which may be at most a year before the ultimate clinical diagnosis of dementia consistent with Alzheimer’s. We took a completely data-driven approach and measured every variable imaginable in both our brain imaging measure and in cognitive/memory testing. From all of these variables, we found one very interesting result. What the experts had referred to as a “silent brain abnormality” that is seen in about 25% of “normal elderly” at age 70 was associated with minor memory loss problems that were similar to but much less severe than in the early dementia in Alzheimer’s disease. We knew that the prevalence of clinically diagnosed dementia consistent with Alzheimer’s disease was 25% in community elderly at age 80. Thus, we had a very simple explanatory model that put the causal disease process of Alzheimer’s disease back 9-10 years earlier than anyone had imagined.

The problem was that all the experts who gave out research funding disagreed and would not even give me another grant from the National Institute on Aging to continue this research. For years, nobody did any of this preclinical Alzheimer’s research until about 10 years ago when people started replicating our very same pattern of results with extensions to other brain imaging measures. What is still controversial is whether you can accurately PET image the beta-amyloid putative causal protein in living patients, but it is no longer controversial that Alzheimer’s has an average preclinical period of at least 10 years. Ironically, one of the experts who sat on the very committee that rejected my grant applications suddenly became an expert in preclinical Alzheimer’s disease over the past 5 years. The experts are very often dead wrong. We allow experts to select variables in the RELR algorithm, but our users tell us that they seldom use this feature because they want the data to tell the story. The data are much more accurate than the experts if you have an accurate modeling algorithm.

(Quoted with permission of the author.)